← RevenueBench home
RevenueBench · Behavioral Clustering · 2026-10-20

Model Archetypes — How the Models Actually Behaved

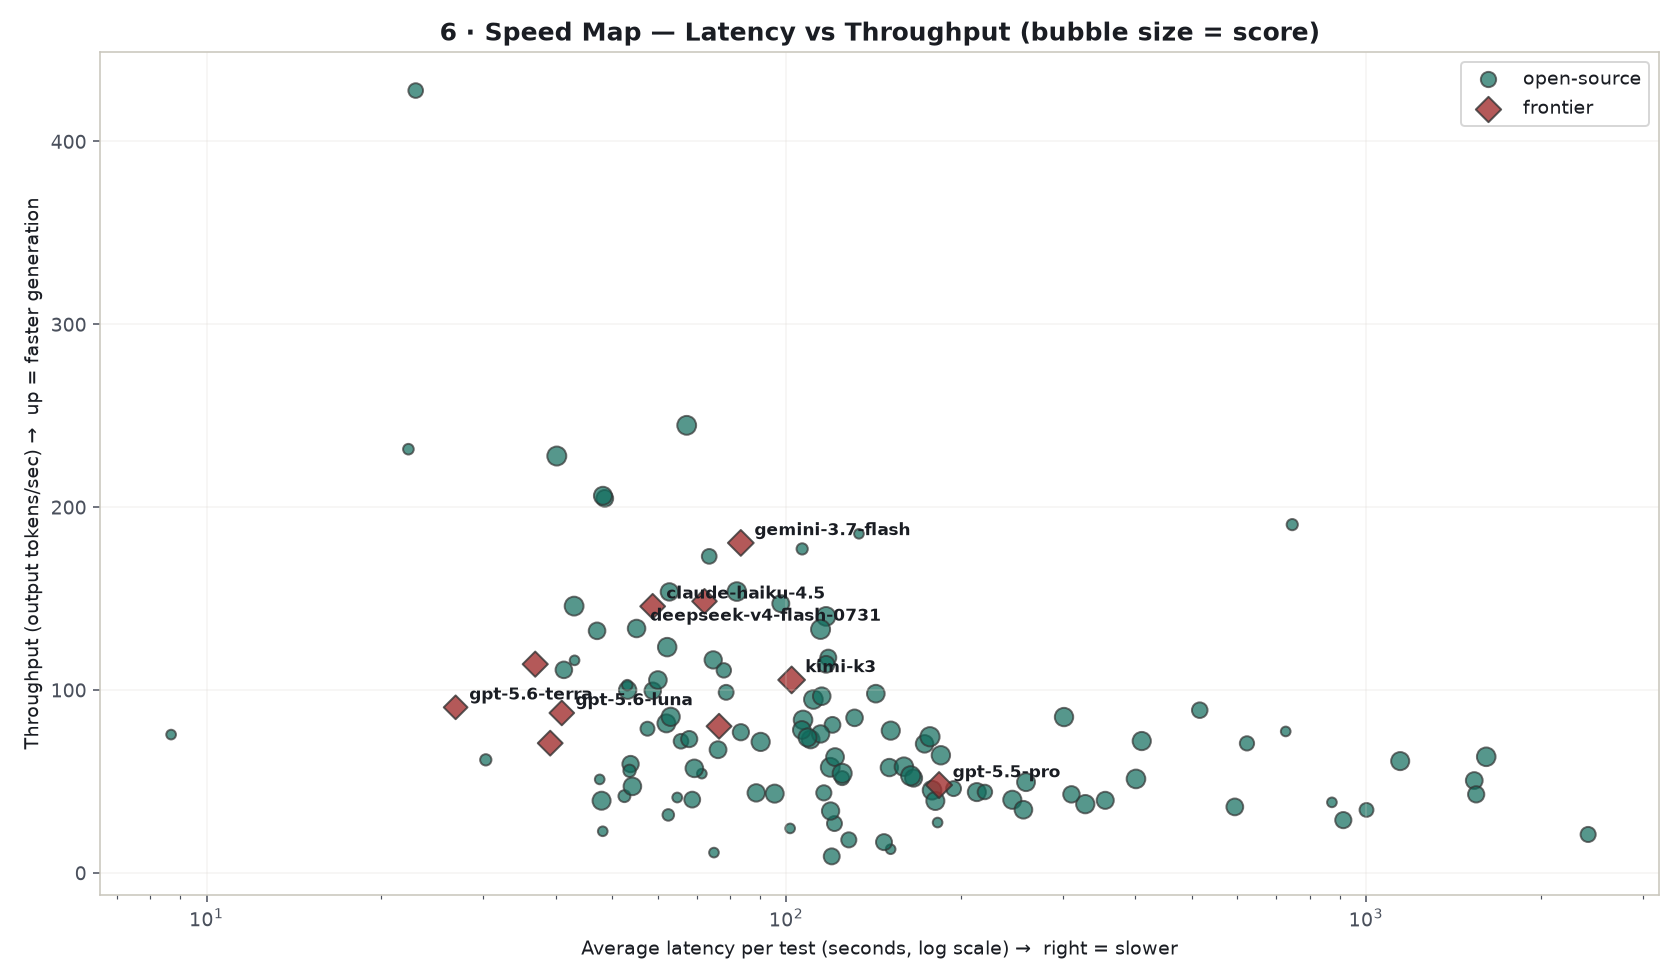
116 models with ≥20 tests, clustered on behavioral dimensions — not just scores: per-category strengths, cost, latency, fabrication events, and math-vs-prose tilt. This is an acknowledgement of observed behavior, not a recommendation. Every model links to its full answer-by-answer record in the Response Reviewer.

Use these profiles conversationally: "these models perform like this." A Complete Analyst behaves like a senior operator; a Fast Communicator writes well but stumbles on rollforward math; Capable-but-Loose models need an entity-validation guardrail. Clustering is k-means (k=6, 20 seeds) over standardized category profiles + log-cost + log-latency + fabrication rate.

The Complete Analysts

43 models
elite-accuracyfastall-around-analyst4 fabrication-events
median mean 0.973median latency 58sstrongest communicationweakest deal & intelligencefabrication events 4
Elite-accuracy, fast, all-around performers. High scores in every category with no weak flank; communication and reporting both strong. These models behave like a strong senior analyst: correct math, disciplined formatting, honest caveats.
ModelMeanLat
meta/muse-wonder0.99628s
deepseek/deepseek-pro-latest0.990177s
elorian/glimpse0.990125s
xiaomi/mimo-v2.6-pro0.989164s
fireworks/ember-10.989125s
meta/muse-spark-1.10.98640s
moonshotai/kimi-k30.985102s
z-ai/glm-5.3-flashx0.983115s
z-ai/glm-5v-turbo0.982154s
unbiased/pareto-26.90.98293s
scaledown/summarize0.98174s
stepfun/step-5-preview0.98193s
google/gemini-3.8-flash0.980117s
qwen/qwen3.8-max-09020.980160s
meta/muse-spark-1.30.97843s
xiaomi/mimo-v2.5-pro0.978119s
meta/muse-spark-open0.978115s
tencent/hy3-preview0.97782s
anthropic/claude-opus-50.976107s
qwen/qwen3.8-flash0.974111s
unbiased/pareto0.97367s
meta/muse-spark-1.20.97362s
z-ai/glm-5.10.973178s
z-ai/glm-5-turbo0.973141s
aion-labs/aion-3.50.972195s
qwen/qwen3.8-omni-flash0.970185s
unbiased/pareto-26.100.96884s
anthropic/claude-opus-4.50.96690s
~unbiased/pareto-latest0.966108s
google/gemini-4-argon0.965139s
anthropic/claude-sonnet-5.50.96448s
xiaomi/mimo-v2.6-pro-ultraspeed0.96448s
google/gemini-3.7-flash0.96283s
qwen/qwen3.8-max-prime0.962109s
xingchen-agi/xing4.0-29b-a4b:free0.962145s
anthropic/claude-opus-4.70.95962s
openai/gpt-5.2-pro0.957181s
deepseek/deepseek-v4.1-flash-10170.95654s
anthropic/claude-opus-4.80.95577s
moonshotai/kimi-k2.7-code0.9531145s
deepseek/deepseek-v4-pro-08130.952110s
xiaomi/mimo-v2.50.95063s
openai/gpt-5.4-mini0.94072s

The Capable but Loose

16 models
strongbudgetprose-over-math6 fabrication-events
median mean 0.924median latency 65sstrongest ops & maintenanceweakest reporting & analyticsfabrication events 6
Strong scores at budget prices, but this cluster carries fabrication events — models that invented a deal or company alias at least once. Correct on most work, but their output needs entity-validation guardrails before it touches production.
ModelMeanLat
minimax/minimax-m3.1-flash:free0.95377s
deepseek/deepseek-v4-flash-07310.95355s
typesafe/jev-router0.94846s
stealth/space-bunny-alpha0.947143s
deepseek/deepseek-v4-flash0.945151s
meta/muse-glimmer-30b0.93898s
stepfun/step-3.5-flash0.928166s
inclusionai/ling-3.0-flash0.92449s
minimax/minimax-m2.50.924594s
openai/gpt-50.921131s
upstage/solar-pro40.91854s
openai/gpt-5-mini0.909120s
google/gemma-4-31b-it0.898516s
liquid/lfm-2.5-24b-a2b0.885111s
google/gemini-3-pro-image0.87366s
google/gemma-4-26b-a4b-it0.8581002s

The Reliable Operators

18 models
elite-accuracybudgetall-around-analyst3 fabrication-events
median mean 0.963median latency 224sstrongest customer & successweakest communicationfabrication events 3
Strong, budget-priced workhorses. Slightly below the elite tier, best on ops-maintenance and routine execution, weakest on data-crm edge cases. Behavior profile: steady, cheap, occasionally thin on the hardest multi-table reconciliation.
ModelMeanLat
inclusionai/ling-3.1-flash0.989238s
z-ai/glm-5.3-prime0.976232s
z-ai/glm-5.3-flash0.972401s
z-ai/glm-5.30.970301s
xiaomi/mimo-v2.6-flash0.968170s
tencent/hy30.9671611s
deepseek/deepseek-flash-latest0.965151s
qwen/qwen3.8-2.4t-a95b0.965259s
deepseek/deepseek-v4-pro0.964328s
qwen/qwen3.8-27b0.962213s
meituan/longcat-2.00.960245s
poolside/laguna-s-2.10.948173s
nex-agi/nex-n2-mini0.9461445s
openai/gpt-5-pro0.932355s
aion-labs/aion-3.5-mini0.932166s
stepfun/step-3.7-flash0.9241536s
ibm-granite/granite-4.2-8b0.916310s
tencent/hy4-preview0.9111548s

The Fast Communicators

3 models
weakfastprose-over-math
median mean 0.772median latency 38sstrongest ops & maintenanceweakest reporting & analyticsfabrication events 0
Budget, fast, prose-oriented. Comfortable writing digests and emails, weak on the heavy reporting math (weighted forecasts, rollforwards). Behavior profile: good words, shaky arithmetic — fit for drafts, not for numbers.
ModelMeanLat
openai/gpt-5-nano0.790106s
openai/o4-mini0.77253s
openai/o30.72043s

The Speed Specialists

34 models
elite-accuracyfastall-around-analyst2 fabrication-events
median mean 0.944median latency 45sstrongest customer & successweakest data & crmfabrication events 2
Budget models built for speed (median 45s) with below-mid accuracy and fabrication risk in-cluster. Trade correctness for latency; usable where a quick pass beats a right pass, with validation.
ModelMeanLat
openai/gpt-5.5-pro0.966183s
anthropic/claude-opus-5.50.96363s
sakana/fugu-ultra0.962410s
openai/gpt-5.50.95937s
openai/gpt-6-astra0.95748s
openai/gpt-6.1-sol-pro0.95542s
scaledown/extract0.95576s
openai/gpt-5.20.953106s
nvidia/nemotron-3.5-super-vl:free0.94945s
openai/gpt-5.4-pro0.947256s
openai/gpt-6-astra-pro0.94669s
openai/gpt-6-sol0.94654s
anthropic/claude-sonnet-50.945115s
openai/gpt-5.6-sol0.94539s
openai/gpt-6.1-sol0.94548s
nvidia/nemotron-3.5-super-vl0.945124s
anthropic/claude-haiku-4.50.94559s
minimax/minimax-m2.10.94260s
openai/gpt-5.6-sol-pro0.94253s
openai/gpt-5.6-luna0.94141s
openai/gpt-5.10.940115s
openai/gpt-5.6-luna-pro0.93875s
anthropic/claude-haiku-5.50.93652s
mistralai/mistral-large-4-00.932189s
openai/gpt-6-sol-pro0.92676s
openai/gpt-5.4-nano0.925117s
openai/gpt-5.6-terra0.92527s
thinkingmachines/inkling0.92147s
openai/gpt-5.6-terra-pro0.92041s
minimax/minimax-m20.91959s
reflection/beam-1.0-501b-a23b0.91470s
openai/gpt-6-luna0.90968s
openai/gpt-chat-latest0.899120s
openai/gpt-6-luna-pro0.87979s

The Fabricators

2 models
weakfastprose-over-math5 fabrication-events
median mean 0.656median latency 39sstrongest ops & maintenanceweakest reporting & analyticsfabrication events 5
Small cluster where every member invented an entity at least once. Scores run low to middling with fabrication risk on top — verify every name and number before trusting output.
ModelMeanLat
amazon/nova-premier-v10.694102s
amazon/nova-pro-v10.61848s

Cost for Value — The Dollar Map

103 full-coverage models
Where price and performance actually meet. The value frontier is the pareto set: no model is both cheaper and better than these.

THE VALUE FRONTIER — cheapest at every score level

ModelMean
meta/muse-wonder0.996
deepseek/deepseek-pro-latest0.990
xiaomi/mimo-v2.5-pro0.978
tencent/hy3-preview0.977
qwen/qwen3.8-flash0.974
z-ai/glm-5.3-flash0.972
minimax/minimax-m3.1-flash:free0.953

VALUE KINGS — ≥0.93 mean at ≤$2 total (12 of 29 shown)

These models deliver top-decile scores at a fraction of premium spend. mimo-v2.5-pro beats the best big-lab scores on this bench (opus-5, gemini-3.8-flash). glm-5.3-flash, tencent/hy3, qwen3.8-flash land within half a point of those scores.
ModelMean
deepseek/deepseek-pro-latest0.990
z-ai/glm-5.3-flashx0.983
xiaomi/mimo-v2.5-pro0.978
tencent/hy3-preview0.977
qwen/qwen3.8-flash0.974
z-ai/glm-5.10.973
z-ai/glm-5.3-flash0.972
qwen/qwen3.8-omni-flash0.970
tencent/hy30.967
deepseek/deepseek-flash-latest0.965
deepseek/deepseek-v4-pro0.964
qwen/qwen3.8-27b0.962

EXCELLENT VALUE — strong scores at modest prices

ModelMean
meta/muse-wonder0.996
elorian/glimpse0.990
fireworks/ember-10.989
meta/muse-spark-1.10.986
moonshotai/kimi-k30.985
scaledown/summarize0.981
stepfun/step-5-preview0.981
google/gemini-3.8-flash0.980
qwen/qwen3.8-max-09020.980
meta/muse-spark-1.30.978

⚠ OVERPRICED — paid the premium, didn't cash it

High spend that the scores didn't justify. gpt-5.4-pro is the priciest run of the entire exercise, 21 of the 29 value kings outscore it. The premium tier's honest pitch is speed and vendor polish — on this bench, not accuracy.
ModelMean
openai/gpt-5.4-pro0.947
openai/gpt-5.5-pro0.966
openai/gpt-5.2-pro0.957
openai/gpt-5-pro0.932
openai/gpt-6-astra-pro0.946
Reading note: this is observed price-performance on these 40 tests, not a vendor verdict — list prices shift, and latency/SLA/enterprise features aren't priced here. The complete dollar map is in the Excel workbook and the value-map chart.